Why Real Time Production Data Demands a Unified Namespace
Walk onto any factory floor built in the last decade and you will see a tangle of protocols, vendors, and databases. SCADA systems talk to programmable logic controllers, edge computing nodes feed dashboards, and historians store years of time-series data. What you will not see is a single source of truth for the one thing everyone needs: real time production data. The data exists, but it is scattered across silos, each with its own schema, latency, and access pattern. That fragmentation costs money, slows decisions, and makes digital transformation feel like a myth.
I have spent years helping industrial companies untangle this mess. The typical story goes like this: a plant manager wants to build a digital twin of a critical process. The equipment is modern, the sensors are installed, and the cloud computing budget is approved. But when the engineering team tries to pull data from the MQTT broker, the OPC UA server, and the legacy SQL database, they find that timestamps do not line up, units are inconsistent, and network routes are undocumented. The project stalls. The digital twin never gets built. The real time production data that should drive it stays locked in its original silo.
The problem with traditional data pipelines
Most industrial setups today rely on point-to-point integrations. A sensor publishes to an MQTT topic; a stream processing engine reads that topic, transforms the value, and writes to a time-series database; a dashboard queries the database and presents a chart. That pipeline works for one use case, but it does not scale. Add a second dashboard, a data lake, or a real-time analytics tool, and you end up duplicating the pipeline. Each new consumer writes its own adapter, its own transformation logic, its own error handling. The result is a brittle web of integrations that breaks whenever a sensor firmware changes or a server is migrated.
I have seen teams try to solve this by dumping everything into a central data lake. That approach trades one problem for another. The data lake becomes a swamp. Without consistent metadata and governance, nobody knows which dataset is current, which field means what, or whether the temperature values are in Celsius or Fahrenheit. The real time production data that should be the foundation of Industry 4.0 initiatives becomes a liability instead of an asset.
The role of a Unified Namespace
A Unified Namespace (UNS) addresses this by providing a single logical layer that connects all data producers and consumers, regardless of protocol or location. Think of it as a data fabric that spans the entire plant, from the sensor on the factory floor to the cloud analytics platform. Instead of building separate pipelines for every pair of systems, you publish once to the UNS and let every authorized consumer subscribe to what they need. The UNS handles the protocol translation, the metadata mapping, and the access control.
This is not a new idea in software architecture. Kafka, for example, has long been used as a central nervous system for event-driven systems. But industrial environments present unique challenges. Latency requirements are tighter. Network reliability is lower. And the protocols are diverse: MQTT for lightweight sensor data, OPC UA for structured equipment data, Modbus for legacy devices, and proprietary APIs for older SCADA systems. A UNS must bridge all of them without introducing a single point of failure or a bottleneck that kills real-time performance.
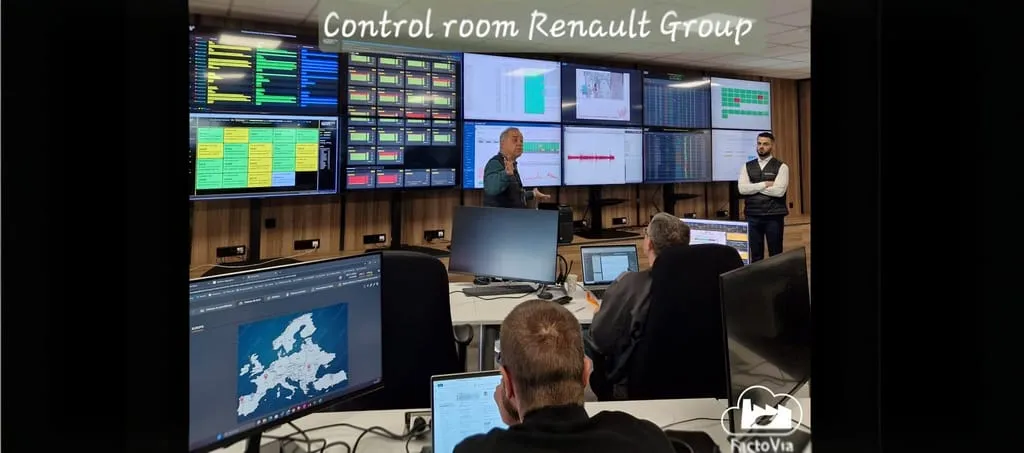
I have consulted on a deployment where a UNS replaced a dozen point-to-point pipelines in a food processing plant. The plant had sensors for temperature, humidity, pressure, and vibration across three production lines. Previously, each line had its own historian and its own dashboard. The maintenance team spent hours every week reconciling data from different sources to diagnose a recurring jam in the packaging machine. After the UNS was in place, they could subscribe to the raw sensor streams, apply sensor fusion to correlate the vibration spike with the temperature dip, and identify the root cause in minutes. The real time production data from all three lines became accessible from a single dashboard, and the digital twin of the packaging line was built in weeks instead of months.
Edge computing and the need for local decision-making
Not every decision can wait for a round trip to the cloud. A robotic arm that needs to stop within milliseconds of detecting an obstacle cannot afford the latency of sending data to a cloud server and waiting for a response. That is where edge computing enters the picture. The UNS must extend to the edge, allowing local stream processing and real-time analytics to run on the same data that eventually flows to the central data lake.
One of the most practical implementations I have seen uses Eclipse Foundation tools for the edge layer. The Eclipse Tahu project, for instance, defines a standard way to publish sensor data over MQTT using Sparkplug. That gives you a plug-and-play model for connecting edge devices to a UNS. The edge processor can apply filters, aggregate values, and trigger alarms locally, while still publishing the raw data upstream for historical analysis and model training. This hybrid approach respects the trade-off between speed and centralization. It also means that a temporary network outage does not halt production; the edge node buffers the data and replays it when the connection is restored.
Data governance and the human factor
Technology is only half the battle. The harder part is getting people to agree on what data means and who owns it. A UNS enforces a common schema, but someone has to define that schema. Someone has to decide which sensor is the authoritative source for temperature in zone A, how often the value should be updated, and what to do when the sensor goes offline. That is a data governance exercise, not a technical one.
I once worked with a chemical company where the operations team and the IT team had been fighting for years over who controlled the sensor data. The operations team saw it as their domain; the IT team saw it as a security risk. The UNS project forced them to sit down and agree on a data dictionary. They defined a naming convention, a set of allowed units, and a retention policy for the time-series database. It was not easy, but the result was a shared language that both teams could trust. Once the governance was in place, the technical implementation became straightforward. The UNS simply enforced the rules that they had agreed on.
Practical steps to get started
If you are considering a Unified Namespace for your own operation, here are a few lessons from the field:
- Start small. Pick one production line or one process area. Map the existing data sources and consumers. Identify the pain points that a UNS would solve. Prove the concept before scaling.
- Choose your protocols deliberately. MQTT is great for lightweight, publish-subscribe patterns. OPC UA is better for structured data and device discovery. Your UNS should support both and bridge between them.
- Invest in metadata. A UNS is only as good as the data dictionary behind it. Define the meaning, unit, and update frequency for every data point. Store this metadata alongside the data in the UNS so that every consumer can discover it.
- Plan for edge cases. Sensors fail, networks drop, and systems restart. The UNS must handle these gracefully. Idempotent publishing, buffered writes, and health checks are not optional.
- Get buy-in from both OT and IT. The UNS sits at the intersection of operational technology and information technology. If either side resists, the project will stall. Early and continuous collaboration is essential.
Beyond the hype
Industry 4.0 has generated a lot of buzzwords: digital twin, sensor fusion, cloud computing, data lake. But the underlying requirement for all of them is the same. You need a reliable, consistent, and low-latency stream of real time production data. Without that foundation, every initiative becomes a custom integration project that costs more than it delivers. A Unified Namespace is not the only way to achieve that foundation, but it is the most practical one I have seen in practice. It respects the diversity of existing systems while giving you a single logical view of your data. And it scales from a single production line to an entire enterprise without requiring a forklift upgrade of every sensor and controller.
The next time your team starts a digital transformation project, ask them how they plan to access the real time production data. If the answer involves a list of custom connectors and a prayer that the data matches, you have a UNS-shaped hole in your architecture. Fill it early, and everything else becomes easier.
Corrections
Spot something wrong? Send it to the desk and it gets fixed in the open.